Medium-large organizations
You'll understand how to extend the governance model with business-unit isolation for larger teams in ~10 min.
Prereqs: Small organizations (read this first, everything below builds on it)
The big picture
The small-organization model holds up while everyone shares the same data boundaries. The moment finance, marketing, and operations all share one Databricks deployment, a single data-engineers group and unprefixed catalogs stop working. Teams wander into each other's development data, grants get confusing, and nobody can tell at a glance which catalog belongs to which department. Prefixes fix this. They add a predictable naming layer on top of the same catalog, schema, and grant model you already know.
Take the small-organization model (three environments, medallion schemas, group-based grants) and stamp a business-unit prefix on every resource. That prefix is a hard naming boundary between departments, and you get it without spinning up separate Databricks accounts.
How it works
Prefixes for isolation
Add a short business-unit tag to workspaces, catalogs, and groups:
| Resource | Example | What it tells you |
|---|---|---|
| Workspace | finance-development | Development workspace, finance department |
| Catalog | finance_dev | Development projects, finance department |
| Group | finance_data_engineers | Data engineers scoped to finance |
The naming makes the boundary visible, so the mistakes stop being silent. Nobody grants finance_data_engineers access to marketing_dev by accident, because the moment the names do not match, the wrong grant is obvious in the review.
Catalogs
Each business unit gets its own set of catalogs per environment.
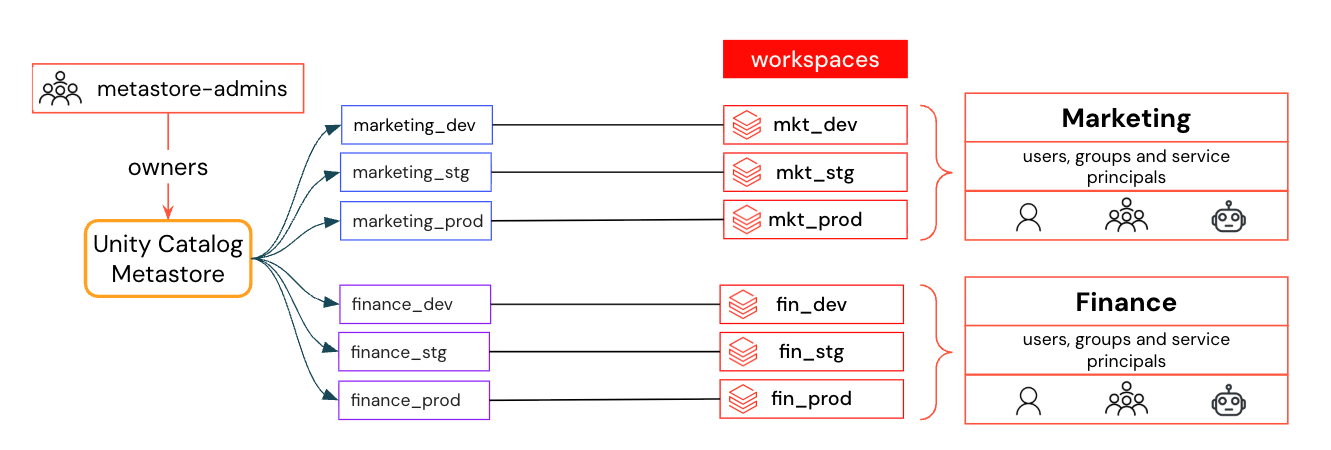
Example for two business units:
- Finance:
dev_finance,stg_finance,prod_finance - Marketing:
dev_marketing,stg_marketing,prod_marketing
The environment rules carry over unchanged: development for experimentation, staging for validation, production for business-critical data.
Schemas
Within each prefixed catalog, schemas still follow the medallion architecture (bronze, silver, gold) per project.
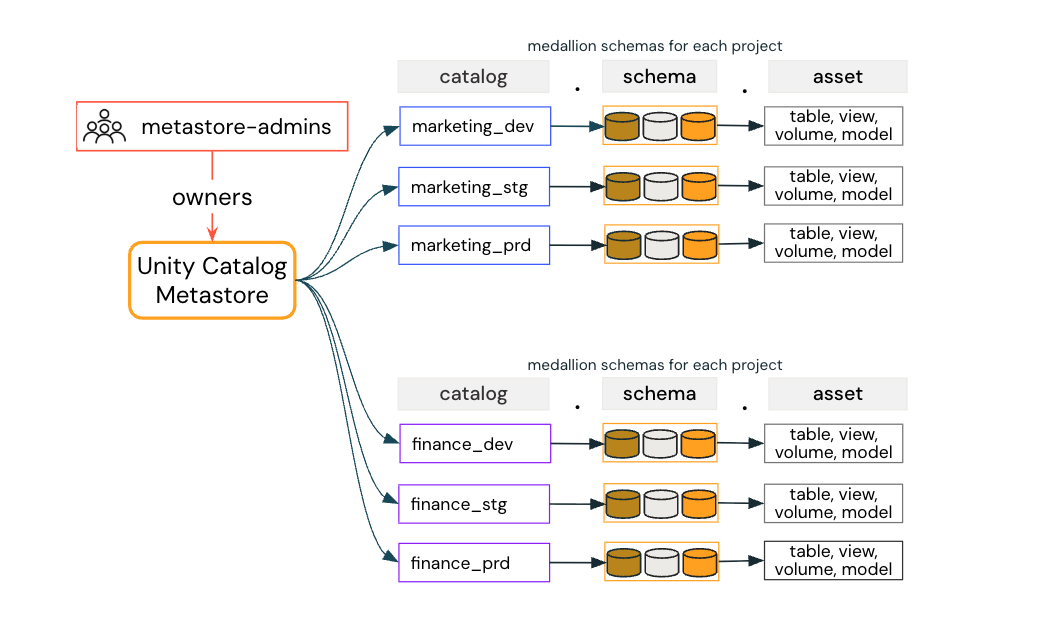
Example: inside dev_finance, a revenue forecasting project uses revenue_bronze, revenue_silver, and revenue_gold.
Permissions and grants
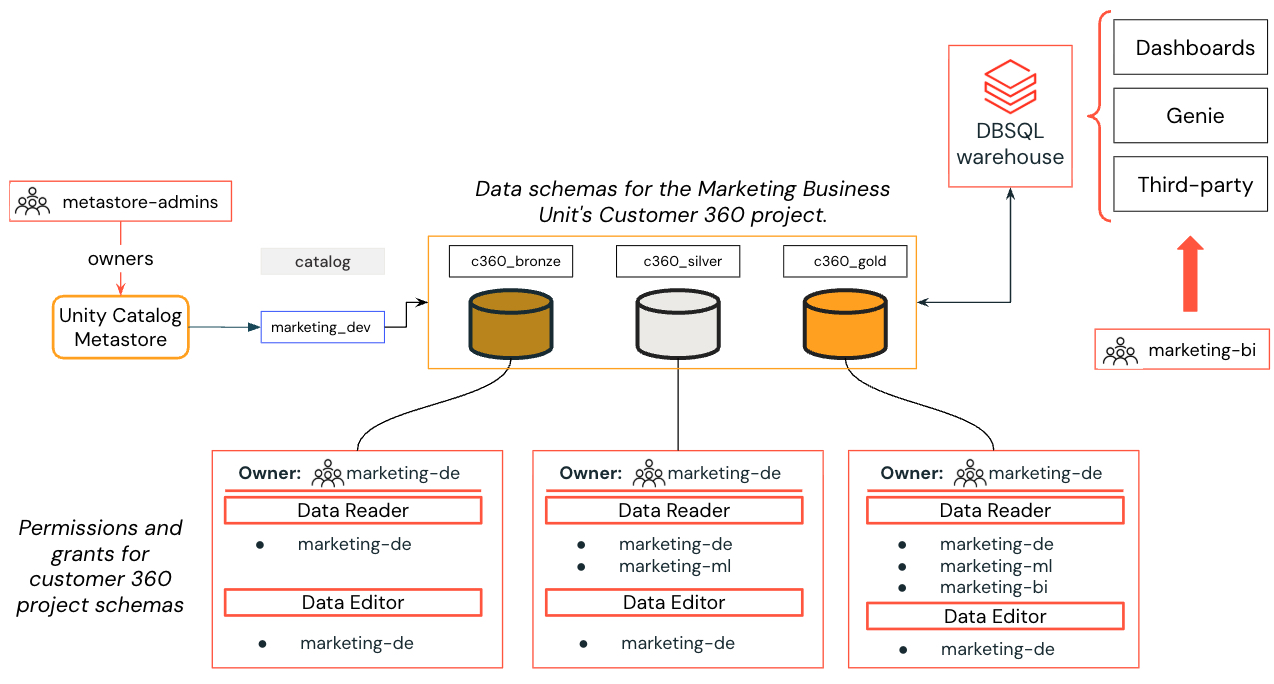
Example: Customer 360 project with prefixed group-based grants.
The grant rules are the same as the small-organization model, with the prefixes attached.
Ownership: the prefixed group that owns the project owns its schemas. So marketing_data_engineers owns c360_bronze, c360_silver, and c360_gold inside dev_marketing.
Sharing: grant at the schema level with Data Reader or Data Editor.
Cross-department access: when finance needs to read marketing data, the marketing schema owners grant finance_data_analysts read access on that specific schema. Because the group and catalog names cross a known boundary, the grant is explicit and easy to audit later.
When to use / when not to
Use this model when:
- Multiple business units share the same Databricks deployment.
- Teams from different departments must not see each other's development data by default.
- You need workspace, catalog, and group names to say who they belong to.
- Audit and compliance reviews want clear ownership boundaries per department.
Stay with the small-organization model when:
- You have a single business unit, or a small team that shares everything anyway.
- Prefixes would add bookkeeping without solving a real isolation problem.
Common pitfalls
Inconsistent prefixes
The whole scheme falls apart if one team writes fin_ and another writes finance_. Pick the prefixes once, write them down somewhere everyone can see, and enforce them. Two to four characters per business unit is plenty.
Duplicating data across catalogs
When marketing needs finance data, the answer is a cross-catalog grant, not a copy of the table sitting in the marketing catalog. Copies drift out of sync, eat storage, and break lineage.
Not scaling groups with the prefix model
Prefixed catalogs with a single flat data-engineers group still leak permissions. Every prefixed catalog needs a matching prefixed group, or the prefixes are decoration.
Next
- Do next: Unity Catalog Setup
- Learn why: Unity Catalog foundations
- Reference: Unity Catalog best practices